01
Pipelines and ELT
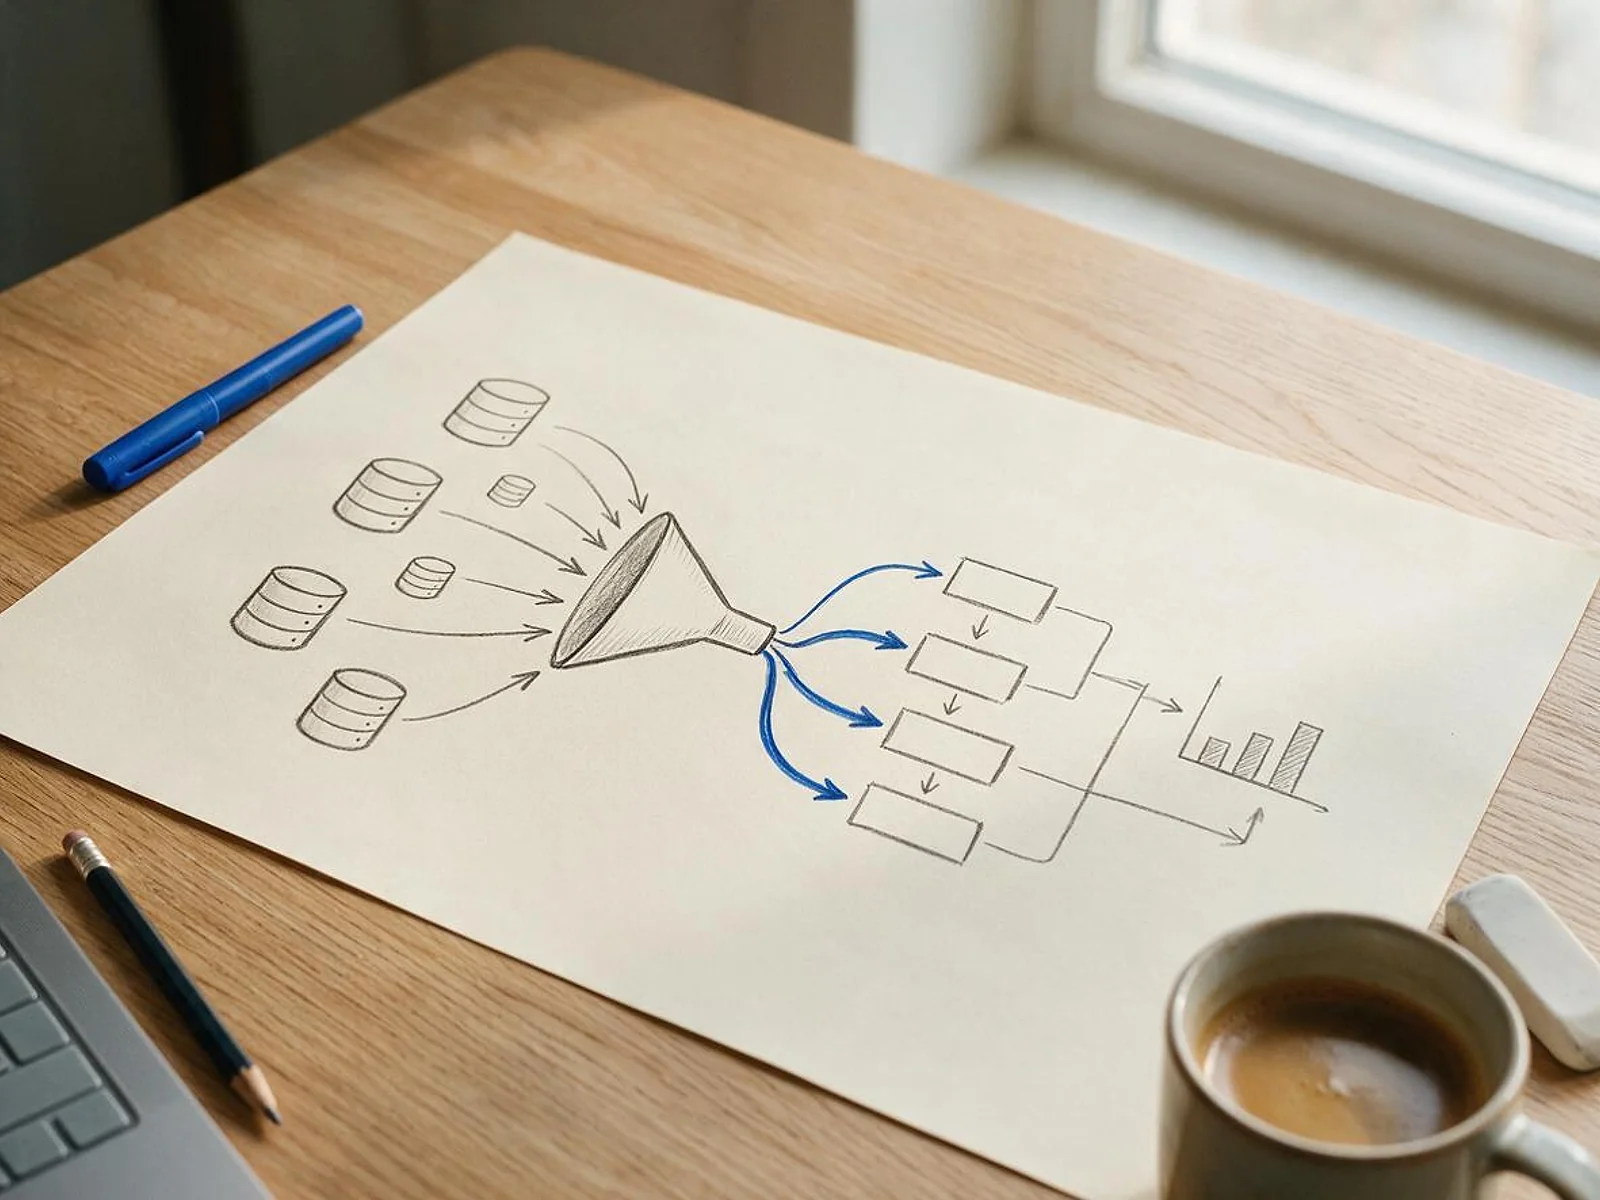
Managed connectors such as Fivetran or Airbyte, or custom Python where no connector exists, loading data from your apps, databases and SaaS tools.
FIG 01 · Data Engineering
ELT pipelines from your apps and SaaS tools, dbt models with tests, and a Snowflake, BigQuery or Databricks warehouse your team can trust, feeding Power BI dashboards and AI features.
See how it works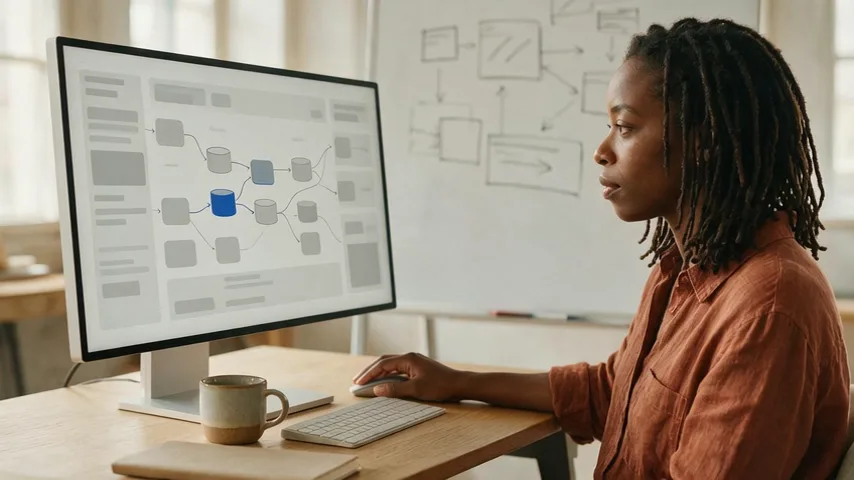
FIG 02 · Quick answer
Data engineering services design, build and run the pipelines that move data from your apps and SaaS tools into a warehouse, clean and model it, and keep it reliable. Elgrith builds ELT pipelines, dbt models with tests, and Snowflake, BigQuery or Databricks warehouses that feed Power BI dashboards and AI features.
FIG 03 · Why it matters
From a Redpoint survey for Fivetran (May 2025, 401 respondents) and dbt Labs’ State of Analytics Engineering 2025.
01
42%
Fivetran’s survey: “42% of enterprises say more than half of their AI projects have been delayed, underperformed, or failed”. The report ties it to poor data readiness.
Source: Fivetran press release, 13 May 2025 (Redpoint survey, n=401)(opens in a new tab)02
56%
In dbt Labs’ 2025 survey, “56% of survey respondents identified data quality as a problem.” Tests and freshness checks are part of every model we ship.
Source: dbt Labs, State of Analytics Engineering 2025(opens in a new tab)03
67%
The same Fivetran survey found “67% of centralized enterprises allocate over 80 percent of their engineering resources to maintaining data pipelines”. Managed connectors and tested models are how we keep upkeep down.
Source: Fivetran press release, 13 May 2025 (Redpoint survey, n=401)(opens in a new tab)FIG 04 · Choose
All three are good. The right one depends on your cloud, your team’s skills and your workloads. We recommend one after an audit, and we hold no partner tier with any of them.
| Snowflake | Google BigQuery | Databricks | |
|---|---|---|---|
| What it is | A cloud data warehouse that runs on AWS, Azure or Google Cloud | Google Cloud’s serverless data warehouse | A lakehouse platform built on Apache Spark and Delta Lake |
| Strongest at | SQL analytics and sharing data across teams | Google Cloud stacks, GA4 and Google Ads data | Large-scale data engineering, machine learning and streaming |
| Skills it suits | SQL and dbt | SQL and dbt | Python, Spark and SQL |
| Watch for | Warehouse sizing and compute credits | Query costs on large scans | Cluster setup and platform complexity |
| Often our pick when | You want one warehouse that works across clouds | You already run on Google Cloud | Machine learning and big data lead |
Already on Microsoft? Microsoft Fabric is an option too, and Amazon Redshift suits AWS-only stacks.
Moving data out of an old system? Read our data migration checklistFIG 05 · What you get
From the first connector to data your dashboards and AI features can trust, built as code you own.
01
02
03
04
05
06
07
08
Deliverables
12
FIG 06 · Example flow
One pipeline, end to end. Every step is code in version control, tested and owned by you.
FIG 07 · Flagship build
Kenerate AI is our flagship build, an all-in-one AI studio designed and engineered by Elgrith. It is not a data warehouse; it shows the AI product engineering that clean data feeds: many models and tools behind one app.
Tools: 23+ studios with guides for every use caseDesigned and engineered by Elgrith
FIG 08 · Quality
56% of respondents to dbt Labs’ 2025 survey named data quality as a problem. We treat quality as a deliverable, not an afterthought.
06principles
dbt tests for uniqueness, nulls, relationships and accepted values, run on every change and every load.
Each source has a freshness target, and a stale source raises an alert before anyone reads an old number.
From source table to dashboard tile, so you can see what breaks when something upstream changes.
Every alert goes to a named owner in Slack or email, with a runbook for the fix.
Role-based access and masking for personal data, designed around UK GDPR and US privacy expectations.
Model and metric definitions generated from the code, so the docs stay current.
FIG 09 · AI
AI features are only as good as the data behind them. We prepare that data as part of the pipeline.
06principles
The documents and tables your AI will use, cleaned, de-duplicated and described.
Documents split and embedded in a repeatable pipeline, not a one-off notebook.
pgvector in your Postgres, or a managed vector database when scale calls for it.
Users only retrieve what they are allowed to see in the source system.
Embeddings update when the source changes, on the same schedule as the rest of the pipeline.
Clean, permissioned data for the AI agents and RAG chatbots we build.
AI agent developmentFIG 10 · Choosing
Questions to ask any data engineering company, us included.
06principles
Ask what happens when a source sends nulls or duplicates. Tests should catch it, not your finance team.
The dbt project, the pipeline code and the cloud accounts should be yours, in your Git and your cloud.
Ask whether their platform advice depends on a partner tier. Ours doesn’t: we hold none.
Warehouse and connector bills grow with data. A good provider designs cost controls from the start.
Data is only useful in dashboards, products and AI. Ask how theirs gets used.
Docs, runbooks and training, so you aren’t locked into the people who built it.
FIG 11 · Process · 7 steps
Start with an audit and a roadmap, or go straight to the build. Either way you get a written scope and a fixed quote first.
Your sources, current reports, pain points, costs and skills. We find what is broken, duplicated or not trusted.
A target architecture, a platform recommendation and a phased plan that starts with the data that matters most. You get a written scope and a fixed quote.
Warehouse, environments, access roles and cost controls set up as code in your cloud account.
Sources connected and raw data landed, with monitoring from the first load.
dbt models for your core entities and metrics, with tests and docs, reviewed in weekly demos.
Dashboards, syncs back to your CRM or AI features built on the tested models.
Runbooks, training and a handover to your team, or ongoing support on terms agreed in your written scope.
FIG 12 · What you get
Written into your fixed quote, so you know exactly what you are paying for before work starts.
12items
FIG 13 · Tech & tools
Proven, well-supported tools, chosen for your project and set up in accounts your business owns.
FIG 14 · Who it’s for
From a first warehouse to an AI-ready platform, in the US, the UK and India.
3 audiences
First warehouse
Growing companies whose reports are spreadsheets stitched from exports, and who need their first warehouse done right.
AI teams
Product and AI teams building RAG, agents or machine learning features who need clean, permissioned data first.
UK teams
UK clients work through our London client partner, with engineering in New Delhi. We design data handling around UK GDPR, with UK or EU hosting regions where you need them.
FIG 15 · Working with us from the USA and UK
Every project gets a point of contact in New York or London and an engineering team in New Delhi. Here is how today’s working days line up, live.
New York
North America
--:--ET
London
UK & Europe
--:--UK
Fixed-scope project
A written scope, one fixed price and a dated plan. Suits websites, apps and MVPs.
Dedicated team
Designers and engineers on your roadmap every month, billed monthly.
White label
For US and UK agencies: our work, your brand, unbranded deliverables.
Calls on ET or UK hours
FIG 16 · Definitions
Two ways to get data into a warehouse. For cloud warehouses, ELT is our default.
| ETL (extract, transform, load) | ELT (extract, load, transform) | |
|---|---|---|
| Where transformation happens | Before loading, in a separate tool or server | Inside the warehouse, after loading |
| Raw data kept | Often not | Yes, so you can replay and audit |
| Typical tools | Traditional ETL suites and custom scripts | Fivetran or Airbyte, then dbt |
| Best for | Data that must be masked before it lands, or legacy targets | Cloud warehouses and analytics |
| Our default | When rules require it | Most projects |
FIG 17 · Freshness
Fresher data costs more to build and run. Pick per use case, not for the whole platform.
| Batch | Micro-batch | Real-time streaming | |
|---|---|---|---|
| Freshness | Hours, such as nightly | Minutes | Seconds |
| Typical tools | Scheduled ELT and dbt | Frequent syncs and incremental models | Kafka and change data capture |
| Cost and complexity | Lowest | Low to medium | Highest |
| Best for | Finance and management reporting | Operational dashboards | Fraud, stock and device data |
FIG 18 · Compare
| Data engineering | Analytics engineering | Data science | |
|---|---|---|---|
| Builds | Pipelines, warehouses and platforms | Tested models and metric definitions | Statistical models and experiments |
| Main tools | Fivetran, Airbyte, Kafka, Airflow, Python | dbt and SQL | Python, notebooks and ML libraries |
| Output | Reliable, fresh data in the warehouse | Clean tables for dashboards and analysis | Forecasts, predictions and insights |
| You need it when | Data lives in many systems | People argue about which number is right | You have clean data and a question to predict |
FAQ
Straight answers about Data Engineering with Elgrith.
Data engineering services cover connecting your data sources, loading data into a warehouse or lakehouse, modeling and testing it with tools like dbt, orchestrating and monitoring the pipelines, and serving the results to dashboards, applications and AI features. Elgrith also handles data migration, real-time streaming and the access controls around personal data.
FIG 19 · Related
Free 30-minute call
Tell us where your data lives today and what you want from it. After a free audit call you get a written scope, a platform recommendation and a fixed quote.
Pick a day. You'll choose a time in your own time zone on the next step.